Category: Uncategorized

  • Using Twitter’s Lead-Gen Card to Recruit Beta Testers

    Using Twitter’s Lead-Gen Card to Recruit Beta Testers

    It turns out that it’s pretty easy to co-opt Twitter’s Lead Generation card for anything where you want to gather a bunch of e-mail addresses from your Twitter community. I was looking for people willing to alpha test a little side project of mine, and it worked great and didn’t cost anything.

    The tweet itself:

    I created it pretty easily:

    1. First, go to ads.twitter.com, log in, and go to “creatives”, then “cards”.
    2. Click “Create Lead Generation Card”. It’s a big blue button.
    3. You can include a title and a short description. Curiously, you can also include a 600px by 150px image. This seems like an opportunity to say a bit more about what you’re doing.
    4. You do have to set up a privacy policy URL. I used a simple google doc.
    5. You also need to configure a fallback URL, which is where people will go if they don’t have a Twitter client capable of the one-click signup. I used a Google form, which let people give me their e-mail addresses directly.

    And that’s it! Tweet enthusiastically, then wait patiently, because if you don’t integrate your Twitter card with your CRM, you have to wait ~24 hours for the download link to appear in the Twitter cards manager. The resulting CSV looks like this:

    Timestamp,User id,Name,Twitter handle,Email
    2013-12-12T23:36:05,774485611,Robots Rule,RobotzRule,h+robots@bit.ly

    A little bit of awk later and I had a list of e-mails ready to go. I ended up getting 49 responses through the Google form and 197 through the Twitter card. It was easy and I’ll definitely do this next time I need to collect people’s e-mail addresses for a project.

  • Books Recommendations for Programming Excellence

    Yesterday I asked people on twitter for recommendations for things to read to improve as a programmer. I’m looking mainly for things on the philosophy side of software engineering. I do realize that practice is the most important thing, but sometimes you run into a design question and it’s always helpful to realize that very smart people have, indeed, thought about these things before.

    I assembled the book recommendations into a bitly bundle. I’ve only read a few of these (generally the older books) and so I can’t recommend specifics, but if you’d care to take a look here they are!

    If you see something that you think should be included, please do let me know in the comments and I’ll add it to the list.


  • The DataGotham 2013 Videos are up!

    I’m happy to be able to share that the full set of videos from DataGotham 2013 are now on youtube.

    The talks are a wide perspective on the interesting work happening around data in New York, and I believe you’ll enjoy all of them!


  • What Mugshots Mean For Public Data

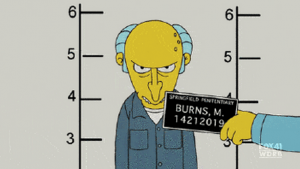
    mrburns_mughost.png

    The New York Times has a story this morning on the growing use of mugshot data for, essentially, extortion. These sites scrape mugshots off of public records databases, use SEO techniques to rank highly in Google searches for people’s names, and then charge those featured in the image to have the pages removed. Many of the people featured were never even convicted of a crime.

    What the mugshot story demonstrates but never says explicitly is that data is no longer just private or public, but often exists in an in-between state, where the public-ness of the data is a function of how much work is required to find it.

    Let’s say you’re actually doing a background check on someone you are going on a date with (one of the use cases the operators of these sites claim is common). Before online systems, you could physically go to the various records offices, sometimes in each town, to request information about them. Given that there are ~20,000 municipalities in the United States, just doing a check would take the unreasonable investment of days.

    Before mugshot sites, you had to actually visit each state’s database, figure out how to query it, and assemble the results. Now we’re looking at an investment of hours, instead of days. It’s possible, but you must be highly motivated.

    Now you just search, and this information is there. It is just as public as it was before, but the cost to access has become a matter of seconds, not hours or days, and we could image that you might be googling your date to find something else about him and instead stumble on the mugshot image. The cost for accessing the data is so trivial that can come up as part of an adjacent task.

    The debate around fixing this problem has focused on whether the data should be removed from the public entirely. I’d like to see this conversation reframed around how we maintain the friction and cost to access technically public data such that it is no longer economically feasible to run these sorts of aggregated extortion sites while still maintaining the ability of journalists and concerned citizens to explore the records as necessary for their work.


  • Learn to Code, Learn to Think

    I recently had a tweet that’s caused a bit of comment, and I wanted to expand on the point.

    I’m a huge fan of the movement to teach people, especially kids, to code.

    When you learn to code, you’re learning to think precisely and analytically about a quirky world. It doesn’t really matter which particular technology you learn, as long as you are learning to solve the underlying logical problems. If a student becomes a professional engineer, their programming ability will rise above the details of the language, anyway. And if they don’t, they will have learned to reason logically, a skill that’s invaluable no matter what they end up doing.

    That you can apparently complete a three month Ruby bootcamp and get a job today is an artifact of a bizarre employment market, and likely unsustainable. But by dedicating three months to learning to think in a logical framework, you’ll also gain an ability that will open opportunities for you for the rest of your life.